CHAPTER 18/ 45
Volatility Modeling and Forecasting
Roadmap: First distinguish variation already realized along a path from conditional variance at a point in time. Then use recursions that read only past information to turn risk estimates into next-period forecasts. Prerequisites: probability (Chapter 6), statistics (Chapter 7), and time series (Chapter 16); Chapter 17 provides background, and this chapter does not use unit-root, cointegration, or VAR results. After completing this chapter, you should be able to check units and timestamps; calculate realized variance, EWMA, ARCH/GARCH, and multi-step forecasts by hand; distinguish persistence from moment conditions; explain high-frequency sampling error; and read a historical crisis-window forecast comparison with appropriate caution.
1. Chapter Objectives
By the end of this chapter, you should be able to:
- Explain that realized volatility is a post hoc measure of a path, whereas conditional volatility is a forecast object given an information set; the two are not equal merely because both are called “volatility.”
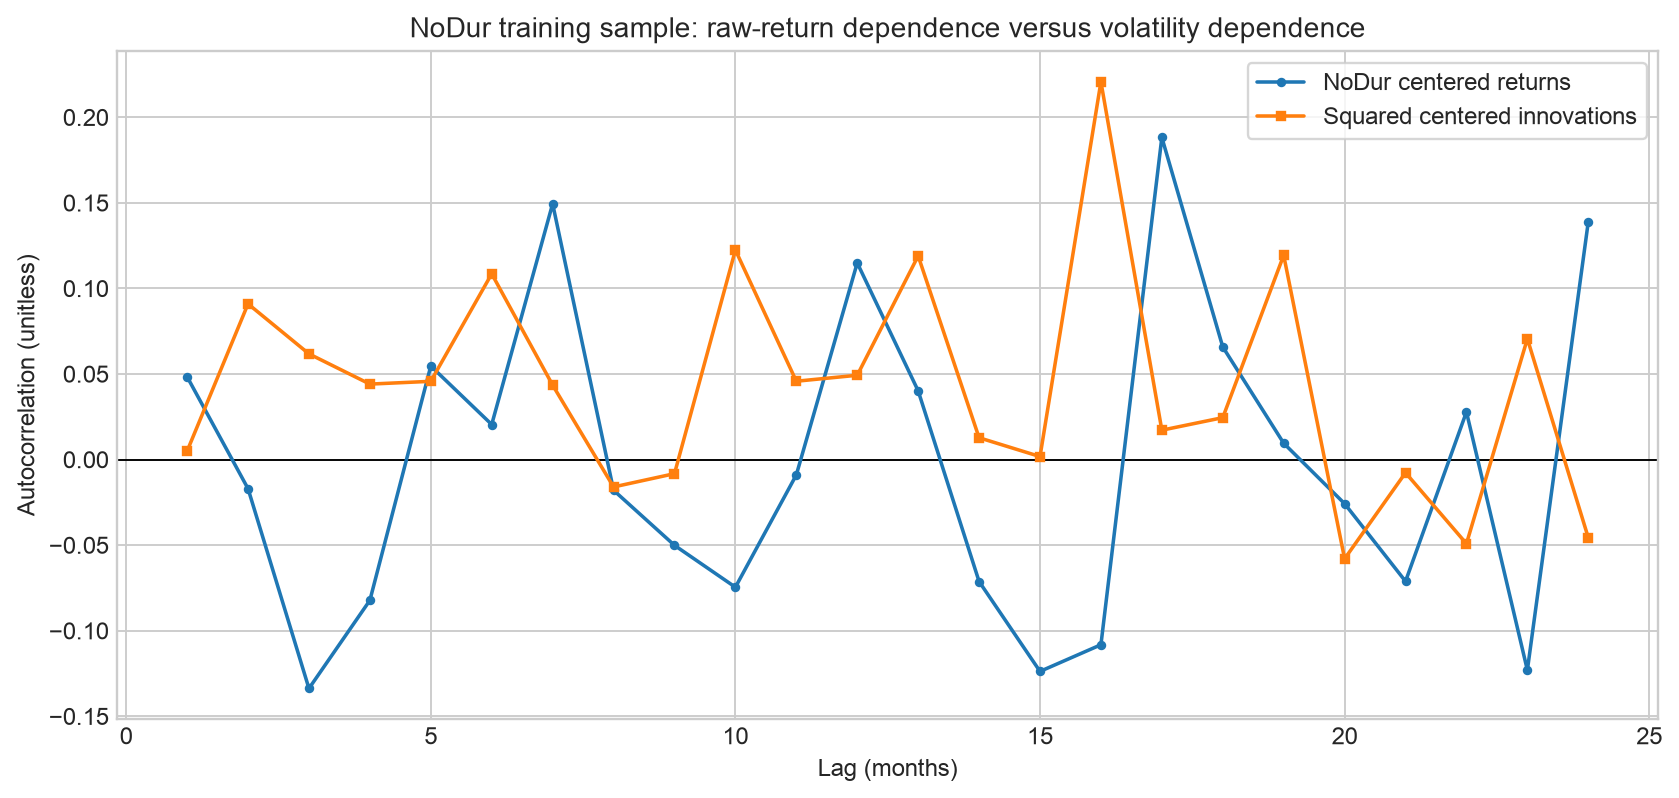
- Understand volatility clustering from the autocorrelation of squared returns, and explain how returns themselves can be nearly uncorrelated while squared returns are clearly correlated.
- Compute rolling variance, exponentially weighted moving average (EWMA), autoregressive conditional heteroskedasticity (ARCH), and generalized ARCH (GARCH) without leaking information across the clock.
- Derive the finite unconditional variance meaning of
, the GARCH multi-step expected-variance recursion, and the fourth-moment condition under a Gaussian assumption; do not conflate these conditions as a single “stationarity” measure. - Explain where the Gaussian conditional quasi-maximum likelihood (QML) objective comes from, the limits of the in-class fit, and why convergence does not imply a global optimum.
- Recheck research conclusions from figures, frozen data, numerical tables, and output files; do not elevate in-sample fit or proxy-loss rankings into statistical significance, trading advantage, or a guarantee about the future.
2. Why Quant Needs This
Return forecasting and risk forecasting are different tasks. Even if tomorrow’s mean return is difficult to predict, today’s market state may still help predict the conditional dispersion of tomorrow’s return. Volatility clustering is an intuitive motivation for this distinction: large moves often occur in clusters during some periods, while calm periods also tend to persist.
If risk is fixed at the full-sample standard deviation, extreme and quiet periods are averaged into one number. If this month’s squared return is used to estimate “this month’s conditional variance,” the target month’s post hoc outcome leaks into the forecast. Rolling, EWMA, ARCH, and GARCH make the information set explicit, provide variance estimates that update over time, and separate the target month from the history available before it.
These methods do not answer “what should I buy?” Volatility is only one risk input. A claim that a position-sizing rule predicts returns or has tradable value would also require records of actual availability, signal-to-order delay, position rules, execution, turnover, financing, borrow, spreads, market impact, capacity, and net returns. This chapter has no trading ledger, so post-cost strategy returns are not applicable.
3. Intuition
Suppose the log returns in three subintervals of one interval are +1%, −2%, and +3%, respectively. Log returns add, so the net log return is +2%, and its square is 0.0004; the sum of the three squared increments is
Conditional variance is like a risk state that updates each period. A large shock yesterday raises the next period’s risk estimate; if the estimate is highly persistent, risk falls back only gradually. EWMA mixes the latest squared shock with the old variance using weights; GARCH also puts the long-run risk level explicitly into the model.
A counterexample helps put this intuition in bounds: observing one very large monthly return today means the squared return is large, but does not prove that tomorrow’s conditional variance must be large. A model of the dynamics is also needed, and the estimated relationship must be reproducible in the target setting. Clustering is a testable pattern of time dependence, not a law that every large decline must be followed by another.
From an Interval Path to a Forecast Clock
The same set of numbers has meaning only together with its interval and information set. Fix the object first, then choose the calculation:
| Object | Input and calculation | Result for the three values | Availability and use |
|---|---|---|---|
| Interval RV | Square each of the three log returns in the same interval and add | 0.0014 | After the interval ends; describes pathwise squared variation |
| Squared net log return | Add first, then square | 0.0004 | After the interval ends; describes the squared net change |
| Three-point sample variance | Mean is 0.0066667; divide the sum of squared deviations by 2 | 0.0006333333 | After all three subintervals; describes the sample dispersion of subinterval returns |
| Monthly innovation squares | Reinterpret the three values as innovations for three months | 0.0001, 0.0004, 0.0009 | Arrive at each month-end; evaluate this month or update next month |
| Monthly conditional variance |
Past information and model recursion | See the three-period forecast in §8 | Before the target month starts; forecasts that month’s conditional risk |
The interval for RV may be one day or one month; the subinterval coverage must be stated. The high-frequency definition in this chapter does not relabel the three rows of a monthly CSV as intraday RV. Although sample variance also has squared-return units, its target is subinterval dispersion; the objects cannot be substituted just because their units match.
| Monthly clock | Known information | Permitted action |
|---|---|---|
| Before month |
Save the forecast for target month |
|
| After month |
Compute the squared-innovation proxy and evaluate the saved |
|
| Update for next month | Recurse to |
To convert units, first multiply decimal returns by 100, then multiply variance by 10,000, and finally take the square root to get volatility in percent. This order ensures
4. Mathematical Foundations
Let
and its units are “decimal monthly return squared.” The conditional standard deviation
Under the classical setup, standardized innovations
Realized variance is often calculated as the sum of squared intraday log returns
5. Formal Definitions
5.1 Realized Risk: Realized Variance and Volatility
Within a clearly specified interval ([t-1,t]), divide the interval into
RV is not demeaned, divided by (M-1), or automatically annualized. It is neither sample variance nor the square of the net return over the full interval. The high-frequency limit relationship between RV and quadratic variation (QV) depends on assumptions about the price process, sampling grid, jumps, and market microstructure. RV on a finite grid will not equal the latent continuous-time integrated variance observation by observation.
5.2 Conditional Heteroskedasticity and Clustering
Conditional heteroskedasticity means that
5.3 Rolling Variance, EWMA, ARCH, and GARCH
Given window
The denominator (W-1) is the rolling sample-variance convention, and the target-month return
The first-order EWMA recursion is
Equivalently, EWMA is ARCH(
Initialization is also part of the forecast rule. Expanding the finite recursion gives
Thus, the influence of
ARCH
GARCH(p,q) also includes lagged conditional variance. This chapter uses
The focus in this chapter is GARCH(1,1):
The units of conditional variance are determined by
5.4 Persistence, Moments, and Strict Stationarity
Let
This concerns only a finite second moment. It differs from strict stationarity, under which the joint distribution of the entire process is unchanged by time shifts. For scalar GARCH(1,1), under the usual stochastic-recursion assumptions, the log-contraction condition for a strictly stationary solution is written as
A finite second moment still does not guarantee a finite fourth moment. If
Therefore, “
5.5 QML, Forecasts, and QLIKE
Gaussian conditional QML estimates parameters using a density objective formed each period from the conditional mean and variance. The in-class implementation fixes the training-sample mean first, then optimizes the scaled average objective for the variance recursion. It omits a constant; when the return scale changes, only
Define the QLIKE (quasi-likelihood loss) for a positive variance forecast
The common “robust ranking under an unbiased proxy” property requires conditions such as
6. Derivations
6.1 Why a Fine-Grid Sum of Squares Is Related to QV
For a discrete log price
6.2 How Microstructure Noise Can Make “Higher Frequency” Worse
Write the observed log price as
If the noise is independent and identically distributed and independent of efficient-price increments, the cross-term has expectation zero after squaring and summing, while the noise-increment variance is
Therefore,
6.3 Step-by-Step EWMA and GARCH Updates
EWMA updates next month’s risk only after
GARCH also starts from the previous
Take expectations and, under a finite second moment and standardized shocks with variance 1,
which requires
6.4 Multi-Step Forecasts Are Not Cumulative Variance Across Periods
At time
Substitute the unconditional level (
Each value for garch_variance_forecast returns the former quantity.
6.5 From a Density to the Gaussian QML Objective
The conditional normality assumption gives
Maximizing
and multiplies the fitted
When the mean and variance dynamics are correctly specified, the process satisfies the required stationarity and ergodicity, identification, integrability, and other conditions, conditional normal QML may yield consistent variance parameters. Under nonnormality, inference for variance parameters also requires a matching robust covariance estimator or stronger distributional conditions. The in-class function has no robust standard errors; it does not prove automatic validity for all nonnormal errors.
6.6 Check Proxy Eligibility Before Comparing Forecasts
Let the true conditional mean be
The cross-term is zero because
| Check | Squared return / fixed-mean squared innovation | High-frequency RV |
|---|---|---|
| Information coverage | One net move per month | Multiple path increments in the target interval |
| Available ex post? | After month-end | After sampling over the target interval is complete |
| Proxy eligibility | Key conditions are conditional mean, centering, and conditional unbiasedness | Key conditions are sampling noise, interval coverage, and the conditional target |
| Fair loss comparison | Same target months, same effective sample, same squared-return units | Same, and check whether it matches the monthly forecast |
If returns are uniformly multiplied by
7. Financial Interpretation
Conditional volatility describes the risk scale for “how far the next-period return may lie from its conditional mean, given the information at this point in time”; it does not describe return direction. If
A high
EWMA is easy to interpret, fast, and parsimonious, but its
8. Numerical Example
9. Python Implementation
Default Standalone Entry Point
From the root directory of the bundled reader package, create an independent environment following its environment instructions, then run:
.venv/bin/python run_notebook.py notebooks/ch18_volatility.ipynb
First use the three log returns from the same interval to check RV, then reinterpret the same values as innovations over three months and check EWMA, ARCH, and GARCH. The multi-step forecast uses a separate, manually constructed GARCHFit: next-month variance 0.0004, training endpoint 2000-03, and 60 observations are toy metadata, not the result of fitting three observations and not a continuation of the third-month variance 0.000322 just calculated. This standalone example returns month-by-month variances of 0.0004, 0.00037, and 0.000343; 60 does not represent the sample size of a fit performed in this run.
It then constructs 360 months starting in 1980-01 using seed 20261018, mean 0.005, omega=0.00001, alpha=0.1, beta=0.8, and a 500-period burn-in; a finite burn-in is not the same as drawing an exact stationary initial state. The first 240 months are used for fitting and the final 120 for evaluation. The training mean is fixed first, then GARCH is fitted on the training segment; QLIKE is reported separately for the known true variance and squared-innovation proxy over the same evaluation period. Shape checks in the loss function do not replace callers’ responsibility to align observations by target month.
By default, the Notebook writes one file: constructed_simulation.csv. Its directory is runs/ch18_volatility_<uuid>/: all 360 rows retain the true variance and sample_role, the forecast column has values only in the last 120 rows, and the training prefix retains NaN. It does not write a historical forecast CSV, a results JSON, or four PNGs; the historical figure set is explicitly skipped. The four figures and NoDur numbers in Sections 10–11 are retained as frozen chapter reference material and are not products of this run.
RUN_FRENCH=False; French data is not read or downloaded by default. Importing the chapter workflow does not mean that its historical market analysis has been executed. The chapter run directory differs from the runs/execution_<uuid>/ directory created separately by the runner; the latter holds an execution copy and state. In-package assertions let readers check constructed calculations; production tests not included in the package do not need to be restored. Constructed results do not demonstrate market forecasting or a post-cost trading advantage.
The CLI below follows the historical course-work root workflow and requires suitable, authorized data inputs and an environment; it does not replace the default command above.
Shared Implementation and Historical Work-Root Workflow
The workflow calls only the shared implementation in src/quant_course/volatility.py; the chapter script handles frozen-data reading, sample splitting, outputs, and plots. It does not write a separate estimator. The script code/ch18_volatility.py locates the project root from its file path and can be launched from any current working directory:
.venv/bin/python /absolute/path/to/quant_course/code/ch18_volatility.py
To select custom output directories:
.venv/bin/python /absolute/path/to/quant_course/code/ch18_volatility.py \
  --output-dir /tmp/ch18-results --figure-dir /tmp/ch18-figures
The script first checks the SHA-256 hashes in the manifest for the raw ZIP, extracted CSV, and processed CSV; if any file is missing or any byte has changed, it stops. It does not download data again or overwrite raw data. It reads decimal monthly returns, splits the sample by full monthly calendar, then outputs fitted parameters, monthly variance forecasts, proxy losses, and four figures. The simulated sample uses fixed seed=20261018; the function retains true conditional variance for each period for auditability only.
The sequence is: train=1990-01…2006-12; the training mean is computed from the training segment only; GARCH is fitted only on the training segment; each target month’s recursion uses return shocks observed before it; and the test squared-innovation proxy can be computed only after the target month ends. This information structure is a post hoc attribution of “what would have happened if historical parameters had been fixed and previous historical shocks had been observed.” The download time, version-availability time, publication lag, and historical local-ingestion time for the French snapshot have not been reconstructed, so this is not a point-in-time real-time backtest.
The in-sample fitted path for the training period is an ex post state, not a real-time month-by-month training-period forecast. The core fixes the mean at the training-sample mean, and its 3 initialization points do not guarantee a global optimum; numerical bounds such as the normalized lower bound for
10. Reading the Figures
The four PNGs below were generated by the historical chapter workflow and are retained as frozen chapter readings; the default offline Notebook does not regenerate them:
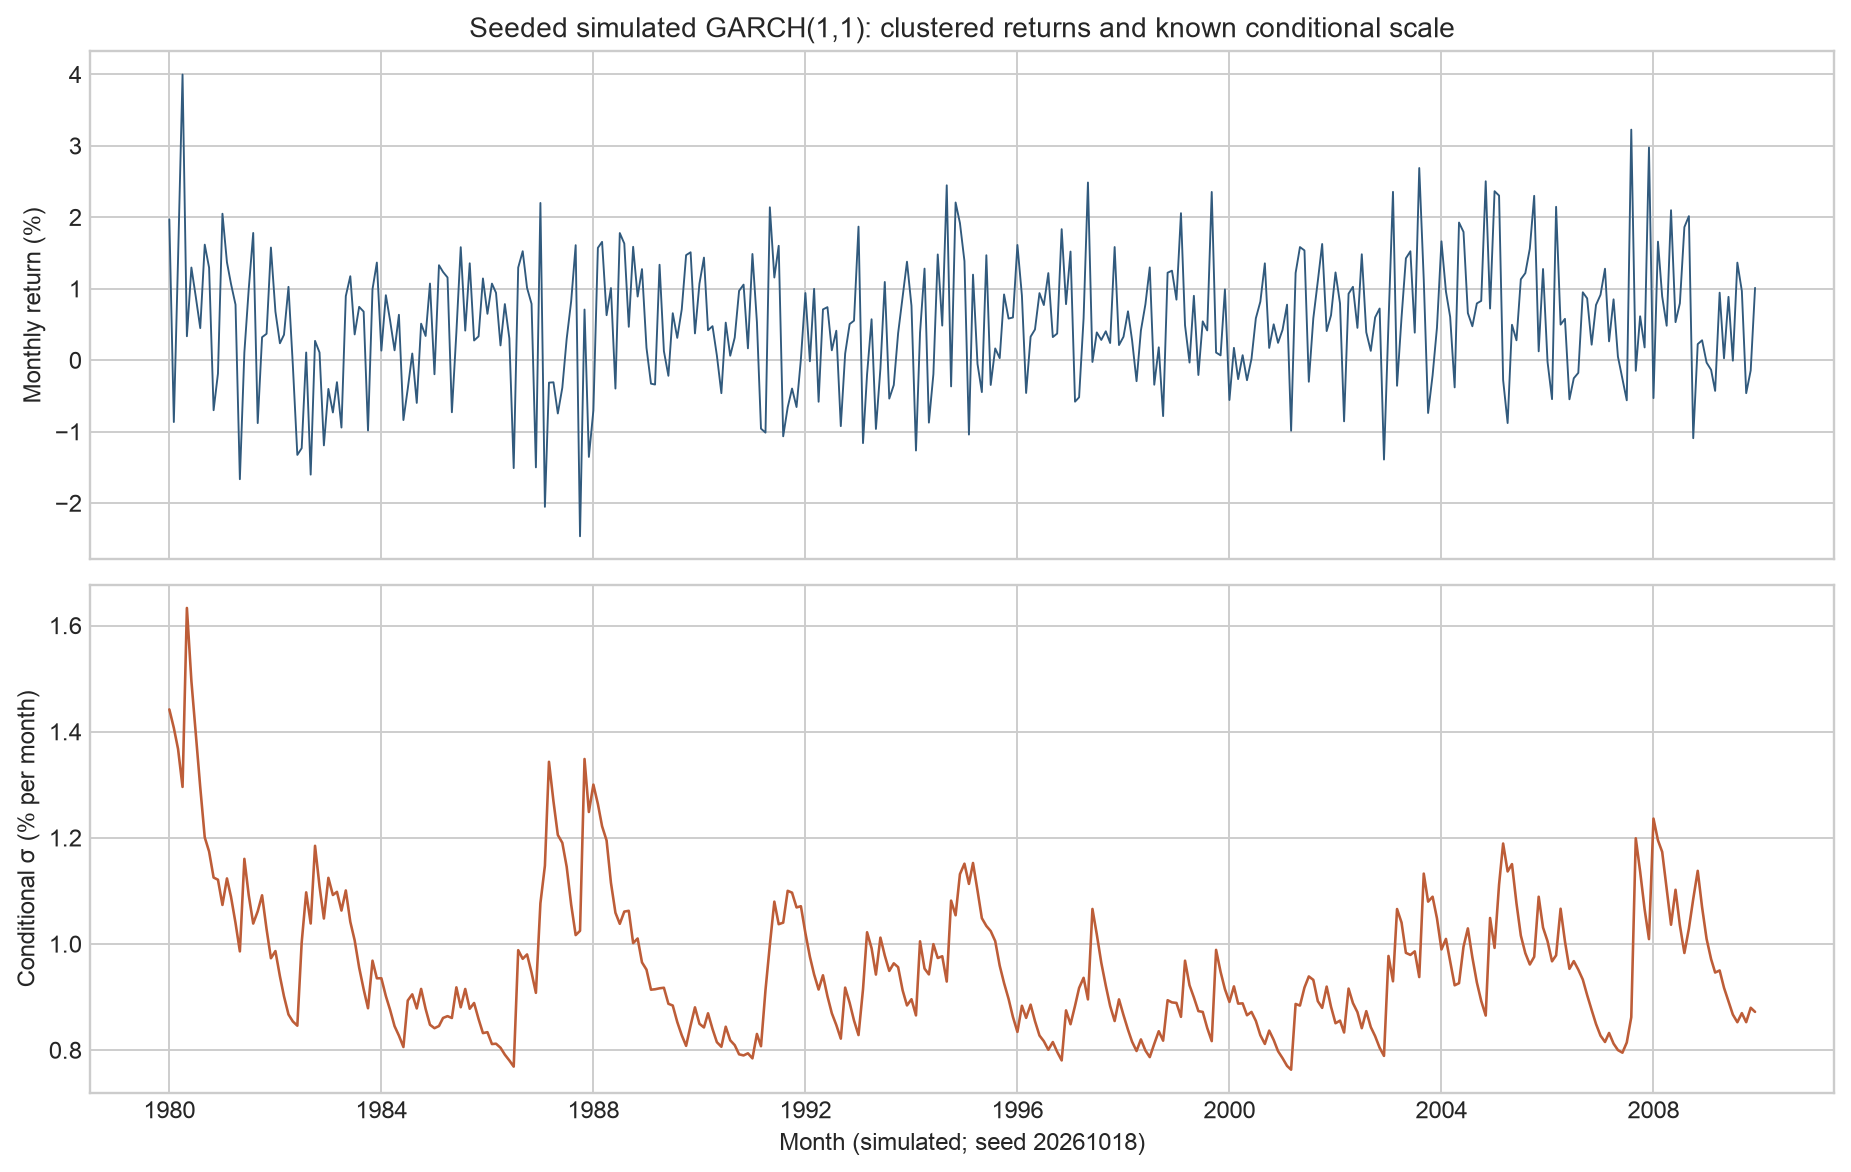
- Simulated volatility clustering: the x-axis is simulated month (seed=20261018); the upper panel shows monthly returns in percent and the lower panel shows the true conditional standard deviation in percent/month. Larger return magnitudes cluster during high-volatility periods. The simulation’s true DGP variance is known, so it is not market evidence; finite burn-in also does not guarantee a strictly stationary initial draw.
- Return and squared-innovation autocorrelation in the real NoDur training segment: the x-axis is lag in months and the y-axis is dimensionless sample autocorrelation; the sample is the 1990–2006 training segment. Squared-innovation autocorrelations are positive at several lags, and both columns fluctuate above and below zero; the figure shows no clear, stable decay pattern. It suggests further checking for conditional heteroskedasticity, but does not establish that volatility clustering has been validated in this segment; the small-sample ACF is not a formal significance test or causal finding.
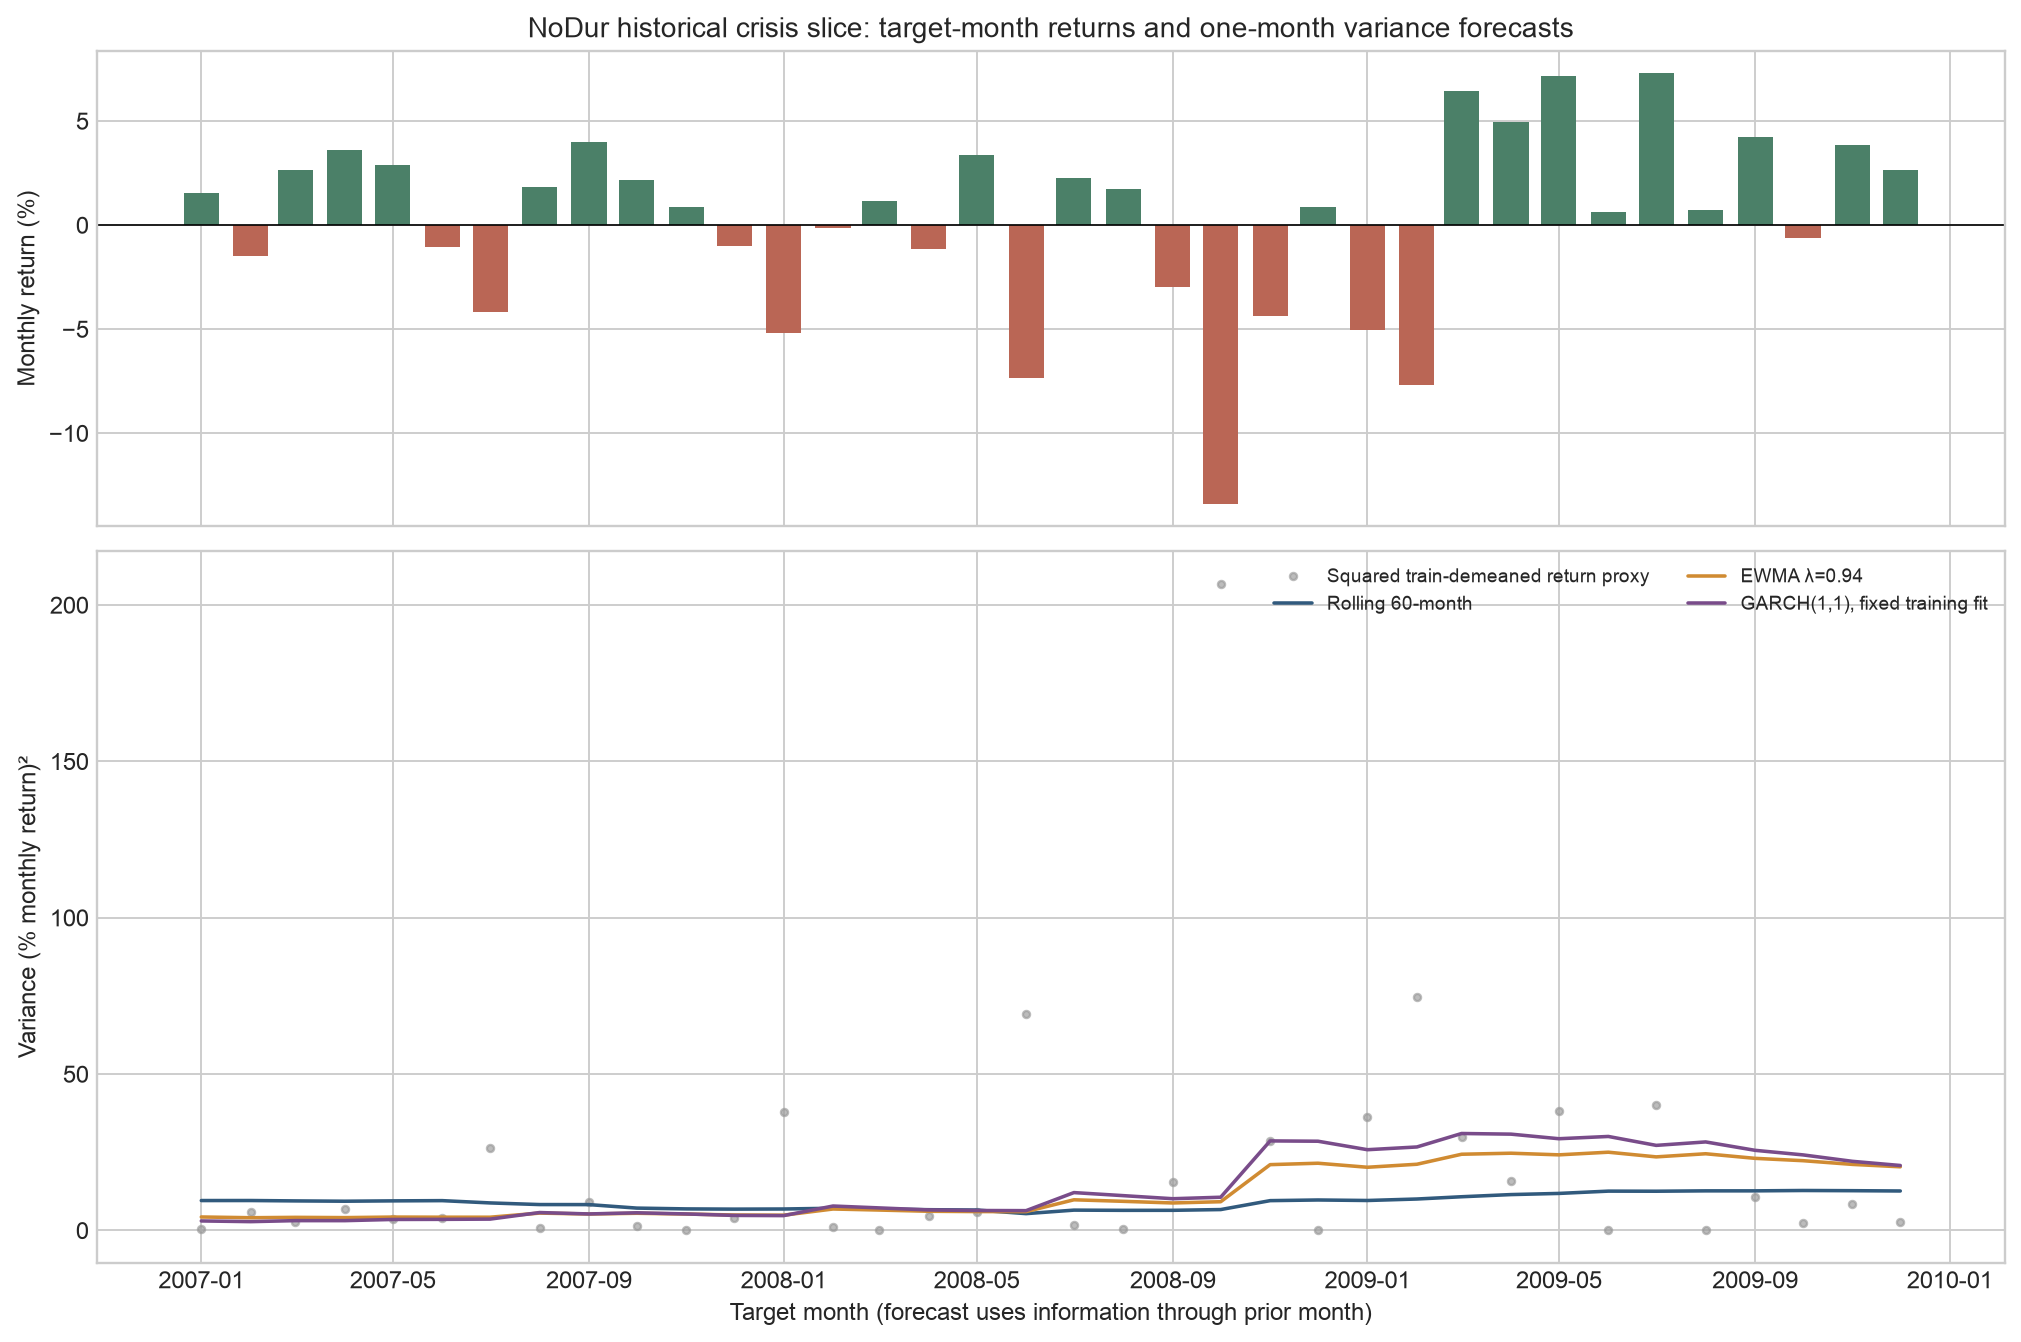
- NoDur crisis-window forecast comparison: the x-axis is target month from 2007–2009; the upper panel shows realized monthly returns in percent and the lower panel shows
, in “percentage monthly return squared.” Gray dots are the post hoc squared-innovation proxy; forecast curves are formed before the target month begins, and the recursion uses that month’s shock after month-end to update the next month. The historical window includes the rise in volatility in 2008, but the proxy is extremely noisy in the figure.
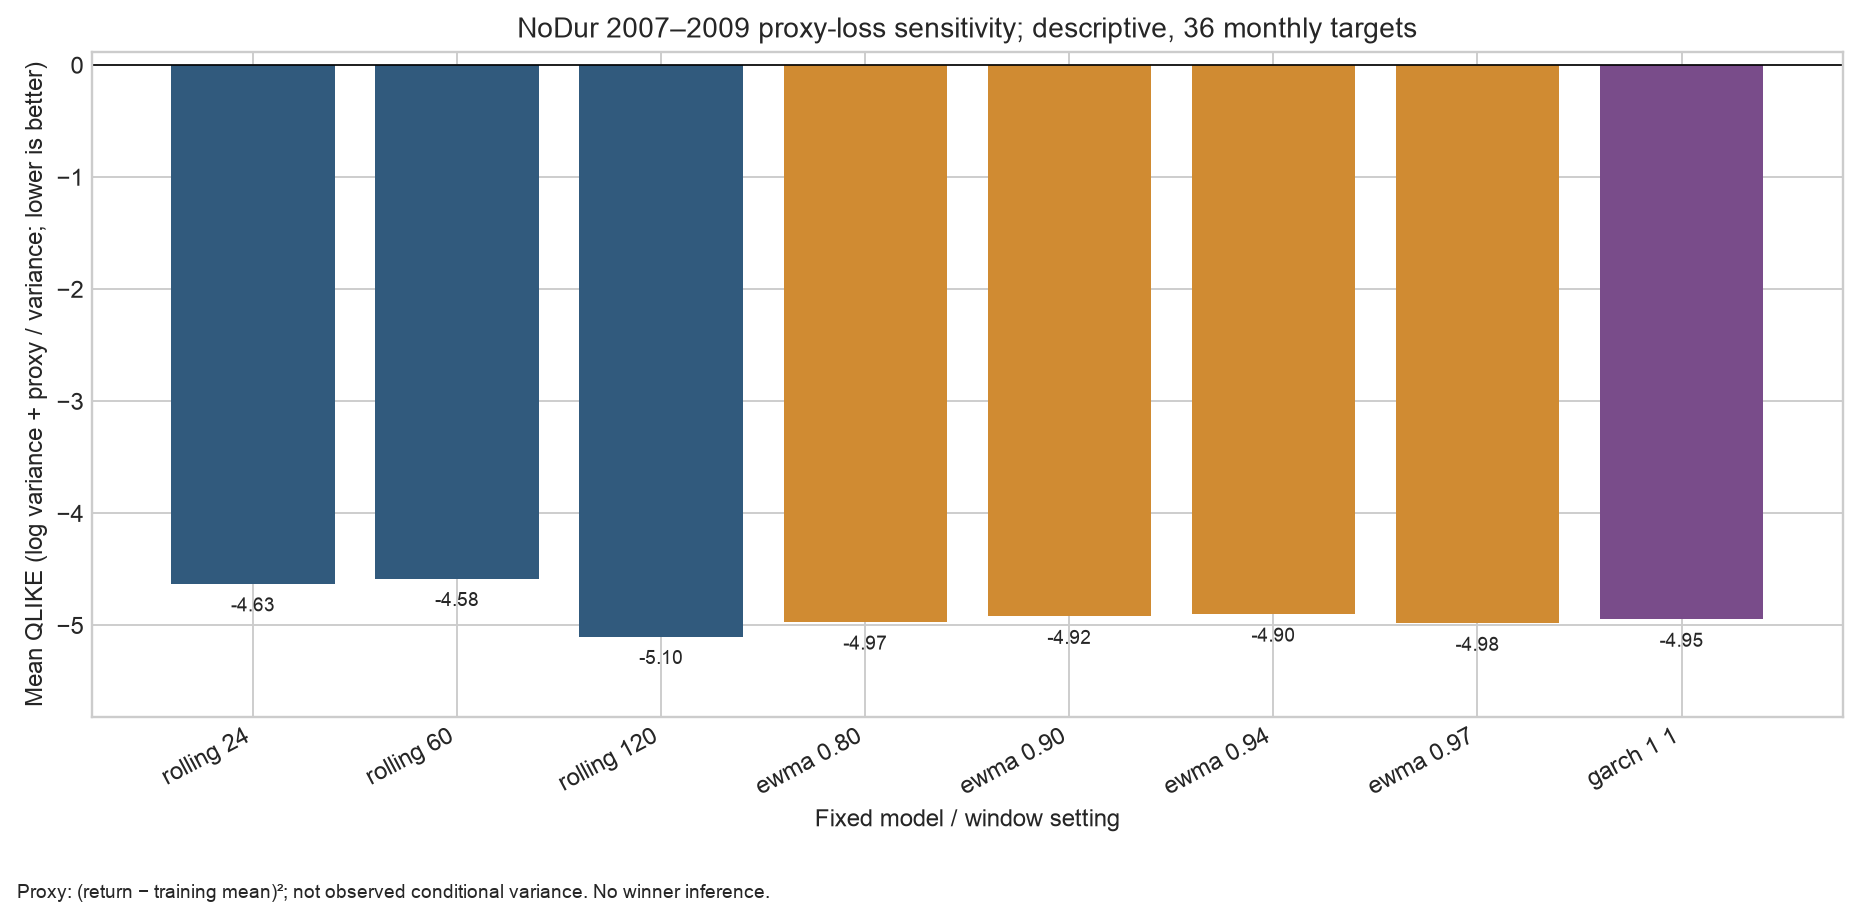
- Proxy QLIKE sensitivity: the x-axis lists fixed model/window settings and the y-axis is average QLIKE over 36 target months; lower scores are better for the same sample and units. The caption identifies the proxy as
, not the true conditional variance. No confidence intervals, significance, or winning-model claim is provided.
11. Real-Market Example
The case uses the French Data Library’s NoDur (Consumer Non-Durables) monthly value-weighted simple returns for the 10 industry portfolios. The frozen snapshot was downloaded on 2026-10-05; the source table is in percent, and the processed table is converted to decimals by dividing by 100. It is monthly data, with return intervals defined by calendar month; the processed data end in 2026-08. NoDur is an industry portfolio rather than an individual stock. Its reported returns do not provide a transaction-cost or tradable-strategy ledger.
| File | SHA-256 | Sample contract |
|---|---|---|
Raw ZIP 10_Industry_Portfolios_CSV.zip |
ebd937a4b995d821867aeb956a96f09a666386f38fa82516b7d1767ee4a49ae5 |
Frozen file as of 2026-10-05 |
Extracted raw 10_Industry_Portfolios.csv |
18ed376fc42e2327ceaf3d65a02521a6512e7f9e3001007c4da69d7db108aa82 |
Official monthly value-weighted table block |
Processed monthly returns french_10_industries_monthly.csv |
3b097d810c295d64eedfa1ece7067ff2a0707f5ca90e33935df9949251f70950 |
1926-07–2026-08, 1202 rows, decimal simple returns |
The research design uses 1990-01 through 2006-12 as a 204-month fitting segment and 2007-01 through 2009-12 as a 36-month historical evaluation segment specified in the script in advance. The historical crisis slice shows how the recursion behaves across a change in conditions; it is not claimed as a preregistered or independent external test. The window also cannot be selected again after seeing the result and then described as prespecified. The fixed training mean for the GARCH fit is 0.0097235, and the training-sample standard deviation is 0.0389174. The fit is:
| Parameter | Estimate | Meaning / units |
|---|---|---|
| 0.000004003 | Constant in decimal monthly return |
|
| 0.091829 | Weight on the new shock square, dimensionless | |
| 0.903517 | Weight on prior variance, dimensionless | |
| 0.995346 | Persistence in the teaching finite-variance model, dimensionless | |
| 0.0008602 | Model-implied long-run variance, decimal monthly return |
|
| 2007-01 forecast | 0.0003050 | Next-month variance after updating with the last training-segment information, decimal monthly return |
For evaluation, use
| Setting | Mean QLIKE |
|---|---|
| Rolling 24 | |
| Rolling 60 | |
| Rolling 120 | |
| EWMA |
|
| Fixed-training-fit GARCH(1,1) |
Rolling 120 has the lowest proxy score here; GARCH does not have the lowest loss. All settings are retained. The sample has only 36 months, squared-return proxies may be conditionally biased, the target slice is affected by crisis conditions, and no paired forecast-loss inference was conducted; therefore, no statistical winner or future trading advantage is claimed. If the mean changes in the evaluation period, the squared deviations centered on the training mean also include mean error. The theoretical conditions for proxy-based QLIKE rankings cannot be assumed to hold as a result.
The clock boundary matters: the forecast
12. Common Mistakes
| Mistake | Why it is wrong | Fix |
|---|---|---|
Treating sum(intraday_returns)**2 as RV |
Netting first lets subinterval moves in opposite directions cancel | Square each subinterval log return and then sum: sum(x*x for x in returns) |
Plotting sqrt(h) as variance or calling h volatility |
The units differ before and after taking the square root | Label variance “return |
Using r_t**2 to forecast h_t for the same month |
The target-month return |
Forecast h_t using only |
| Saying |
This is a finite-second-moment condition; strict stationarity has a different stochastic-recursion condition | Describe finite variance, strict stationarity, and the fourth moment separately; do not conflate them |
| Assuming EWMA |
EWMA corresponds to the boundary |
State that the recursion alone does not pull variance back to a long-run level; compare initial-value effects and shock decay |
| Treating multi-step (h_{T+k | T}) as cumulative future-return variance | The core output is expected variance for each individual month |
| Calling squared returns true volatility | They are noisy proxies, random and possibly conditionally biased | Report model forecasts, observed proxies, and latent conditional variance separately |
Treating optimizer success=True as proof of a global optimum or parameter significance |
Multiple starts do not exhaust the parameter space; there are no standard errors | Report starts, constraints, and objective; do not claim robust inference that was not performed |
| Calling a low QLIKE score tradable profit | The loss is not a position, return, or trading ledger | Separately validate real-time availability, transaction costs, capacity, and net returns; none is available here |
The shortest leakage demonstration is: forecast_t = eps_t**2 uses the target month’s post hoc data on the right-hand side; the correct one-step GARCH expression at the start of month forecast_t = omega + alpha*eps_prev**2 + beta*h_prev. They are not forecasts formed at the same time.
13. Applications in Quantitative Research
A reproducible volatility study should make the following chain clear.
- Hypothesis and target: The question here is how a one-month variance forecast behaves under historical conditions, not whether returns can be forecast in direction or what the portfolio return will be.
- Data and version: Record the French source, download date, unit conversion, missing values, hashes, release dates, and versions. A test of what was historically available requires point-in-time data with publication times and revision versions; the current snapshot is insufficient.
- Clock: Specify the training cutoff month, target month, signal calculation time, and time an order could be placed. A monthly return is observed only after the target month ends. The month-by-month recursion uses the previous month’s actual shock, so future values are not backfilled into earlier forecasts.
- Benchmarks and candidates: Use rolling variance as a benchmark and compare it with fixed-parameter EWMA/GARCH; prespecify candidate settings, retain sensitivity checks, and do not pick a winner from a short evaluation period.
- Diagnostics and loss: Check return and squared-innovation autocorrelation, conditional-standard-deviation paths, optimization boundaries, convergence counts, and units; align target months before evaluating loss. Squared innovations are not the latent true variance; QLIKE ranking has the corresponding theoretical support only under conditions such as conditional unbiasedness of the proxy.
- External validation: Recheck across different markets, periods, frequencies, and structural changes, and report failed months and instability. If converting forecasts into positions, separately analyze actual order timing, turnover, fees, market impact, financing, borrow, and capacity.
- Limits of the conclusion: Statistical differences in forecast loss are not differences in trading utility; without a post-cost ledger, do not calculate “net
.” This case retains the result that Rolling 120 has lower proxy loss than GARCH; it does not repeatedly retest that result to declare a winner.
This chapter has also not run a “look-ahead in the objective” trading experiment: target-period conditional variance is a risk statistic, and no rule for placing trades using it has been defined. There is no trading ledger, so costs are “not applicable,” not “zero.” A reproducible net-
14. Chapter Summary
RV sums the squared increments in an already observed, finely partitioned path; conditional variance
For a finite-second-moment GARCH(1,1) with standardized innovations of variance 1,
The code puts these concepts into practice through the separation of training and target data, data hashes, and the recursive clock. The historical NoDur 2007–2009 comparison shows the difference between a forecast and a squared-return proxy; it cannot establish availability at the time, a winning model, strategy profitability, or a future trading advantage.
15. Exercises
18-E01 Concept: RV and Sample Variance. In one precise sentence, compare interval RV, sample variance, and squared net return; list two path features that can make RV greater than squared net return.
18-E02 Concept: Clustering. Why can volatility clustering exist even if return autocorrelation is close to zero? Give one sample statistic to check and explain what it cannot prove.
18-E03 Concept: Stationarity and Moments. What does each of the following describe: the finite-second-moment condition, strict stationarity, and a finite fourth moment? How do they differ logically?
18-E04 Concept: EWMA. What does EWMA’s
18-E05 Hand Calculation: Realized Risk. For log returns
18-E06 Hand Calculation: EWMA. Let
18-E07 Hand Calculation: ARCH/GARCH. Let
18-E08 Persistence and Higher Moments. For parameters
18-E09 Multi-Step Forecast. For the GARCH model above, if
18-E10 Hand Calculation: Noise Bias. Suppose the expected sum of squared efficient-price increments over the interval is 0.001, each observation-noise variance is
18-E11 QLIKE. Write the average QLIKE. If proxy
18-P01 Implement RV. Pass the three subinterval log returns from the same interval, .0014 and also display the squared net return. Explain why it is not automatically annualized.
18-P02 Forecast Clock. Use four consecutive monthly returns
18-P03 Reproducible Research. Run the chapter CLI from any working directory and check the three input SHA-256 hashes, training and evaluation record counts, results JSON, and four figures. If a hash does not match, explain why the correct behavior is to stop rather than download the data and continue automatically.
18-C01 QML Boundary. Give three differences between core fit_garch11 and joint normal MLE; explain what “three starting points converged” can and cannot establish. List a typical set of regularity conditions for consistent QML variance estimation; do not claim it holds for arbitrary nonnormality.
18-C02 High-Frequency Microstructure. Starting from
18-C03 Historical vs. PIT. Explain why the French NoDur 2007–2009 results in this chapter are neither historical PIT evidence nor a preregistered test. List the ledger fields still needed for a net strategy test, and distinguish “costs not applicable” from “costs are zero.”
18-C04 Constructed Counterexample: Strict Stationarity and Variance. For
Teaching Supplements (Independent IDs)
18-R01 Initialization Effects. Use the expansion in §5.3 for EWMA to prove that the forecast difference from two initial values decays geometrically. If the initial values differ by 0.0005 and lambda=0.9, what is the difference after two updates?
18-R02 Proxy and Unit Diagnostics. The true conditional mean is 0.01, the fixed center is 0, and the true conditional variance is 0.0004. What is the conditional expectation of the squared-return proxy? If returns are uniformly converted from decimals to percentages, by how much does QLIKE increase, and does the ranking change?
18-R03 Research Judgment. A researcher compares intraday RV with a monthly forecast and declares it unbiased because its proxy mean is close to the mean of monthly squared returns. Which conditions and records are missing?
16. Programming Exercises
Complete 18-P01–18-P03. Deliver a runnable cell or script, assertions, run command, Python and dependency environment, output paths, data version, and clock description. P02 must display the target index and NaN warmup; do not silently fill warmup rows with zeros. P03 must not touch frozen raw files or introduce a network download.
17. Challenge Problems
Complete 18-C01–18-C04. Answers may use equivalent reasoning, but must state assumptions, units, information set, and testable steps.
- For full credit on C01, distinguish the fixed training-sample mean from joint MLE; explain that consistency and robust inference are different questions; state at least three of the following: correct conditional mean/variance, stationarity and ergodicity, identification, and finite integrability; and note that the core has no parameter standard errors.
- For full credit on C02, expand the noise difference and squared expectation and propose a frequency-sensitivity plan; identify the limits of the simple derivation, including correlated noise, correlation between price changes and noise, jumps, and asynchronous observations.
- For full credit on C03, identify the missing data version/release times and historical availability, the ex post crisis slice, and the absence of position or execution ledgers; provide at least six net-return audit fields.
- For full credit on C04, use the strict Jensen inequality to distinguish
from ; explain that a strictly stationary solution can exist while the second moment formula is infinite or does not hold; do not present the chapter’s finite-variance implementation as covering this region.
18. Complete Answers and Hints
18-E01
RV is the sum of squared log returns over subintervals within the same interval; sample variance centers on the sample mean and divides by (M-1); squared net return nets the returns first and then squares. Repeated reversals reduce the net amount, and more nonzero subintervals add to the sum of squares, so path cancellation and back-and-forth movement within an interval can both make RV greater than squared net return.
18-E02
If the signs or linear variation in innovations are unpredictable but their conditional scale changes with market conditions, then
18-E03
The finite-second-moment condition
18-E04
18-E05
Net log return
18-E06
The third innovation, .03, generates
18-E07
With
18-E08
The Gaussian fourth-moment left-hand side is
18-E09
These are risk forecasts for one month each. Cumulative interval variance is the sum of monthly variances only under additional conditions, including zero cross-period innovation conditional covariance given the forecast origin and a known mean;
18-E10
The variance of each noise difference is
18-E11
If
18-P01
Reference implementation:
from quant_course.volatility import realized_variance

parts = [0.01, -0.02, 0.03]
rv = realized_variance(parts)
net_squared = sum(parts) ** 2
assert abs(rv - 0.0014) < 1e-12
assert abs(net_squared - 0.0004) < 1e-12
print(rv, net_squared)
Output: 0.0014 0.0004. The function does not demean, divide by the sample count, or annualize; the caller must record the interval and sampling design from which these returns came.
18-P02
import pandas as pd
from quant_course.volatility import rolling_variance_forecast

idx = pd.period_range("2000-01", periods=4, freq="M")
r = pd.Series([0.01, 0.03, -0.01, 0.02], index=idx)
f = rolling_variance_forecast(r, window=2)
assert f.iloc[:2].isna().all()
assert abs(f.iloc[2] - 0.0002) < 1e-12  # sample variance of 0.01 and 0.03
r2 = r.copy(); r2.iloc[2:] = 100.0
f2 = rolling_variance_forecast(r2, window=2)
assert f2.iloc[2] == f.iloc[2]
The month-3 forecast uses only the two observations from months 1 and 2. Their sample variance is
18-P03
Run from a current directory outside the repository:
cd /tmp
/absolute/path/to/quant_course/.venv/bin/python \
  /absolute/path/to/quant_course/code/ch18_volatility.py \
  --output-dir /tmp/ch18-results --figure-dir /tmp/ch18-figures
Check the JSON: train_n=204, evaluation_n=36, training endpoint 2006-12, test window 2007-01…2009-12, the three hashes match the manifest, and the paths to four figures exist. A hash mismatch means the inputs are no longer the frozen evidence for this study; silently downloading a new version would change the research object and its version. The correct action is to stop, report the difference, and establish a separate manifest for the new snapshot.
18-C01
The in-class function first computes and fixes the training-segment sample mean, then optimizes only the variance parameters; joint normal maximum likelihood optimizes the mean and variance parameters together in the same likelihood. The core objective is normalized by the scale of training residuals, omits a constant, and takes the average; after fitting,
Typical consistency conditions can include a correctly specified (or explicitly quasi-correct) conditional mean/variance, a stationary and ergodic process, a finite and integrable objective, identified parameters with a parameter space satisfying the required conditions, and numerical optimization close to the objective’s extremum. Under nonnormality, inference usually also requires a corresponding robust variance estimate; the core provides no robust standard errors. Convergence of an in-sample fit does not replace these theoretical and empirical conditions.
18-C02
Expand
First define the asset, trading hours, and target; select several sampling intervals in advance; estimate RV using the same cleaning, alignment, and interval rules, while retaining jump/noise diagnostics; compare error and robustness across dates and liquidity regimes; where possible, combine estimates of microstructure noise with alternative realized measures; and report estimation uncertainty. Do not generalize one frequency chosen in one paper for one asset to all settings.
18-C03
The data are the current French snapshot downloaded on 2026-10-05, with no historical month-by-month release versions, availability times, or local-ingestion timestamps; historical NoDur values may have been revised. The crisis slice is fixed in the script, not preregistered or an independent external test. Although the parameters are fitted before evaluation begins, the test still uses existing historical target-month returns and later recursive updates; this does not reconstruct real-time operations.
A post-cost strategy also needs: signal time, target weights/positions, executable order time, order/execution prices, spreads and fees, turnover, market impact, financing/borrow, cash/margin, capacity limits, handling of unfilled/delayed orders, and a benchmark and net-return series. Without a strategy and order ledger, costs are not applicable; this does not mean costs were set to zero or that net returns have no costs.
18-C04
Let
Complete Answers to the Teaching Supplements
18-R01. Subtracting the two recursions with the same shock sequence gives
18-R02. The conditional expectation is
18-R03. First check whether intraday RV covers the complete target month, the return definition and units, sampling noise and jumps, whether the forecast was saved before the month, and whether the effective samples match. Unbiasedness requires the conditional expectation to match the target; close unconditional sample means do not prove conditional unbiasedness and do not establish a significant win or net return.
19. Further Reading
- Must Know — Bollerslev (1986), §§2–3. Read the GARCH representation, weak-stationarity variance condition, and GARCH(1,1) fourth-moment condition; the corresponding passages and author-PDF page references for this chapter are recorded in
source_notes.md. - Must Know — Andersen, Bollerslev, Diebold & Labys (2003), Introduction and §2. Read about the asymptotic relationship between high-frequency sums of squared returns and quadratic variation/integrated variance, including the jump term; do not misread a limit result as equality between finite-grid RV and conditional variance.
- Should Know — Hansen & Lunde (2006), Introduction, theoretical framework, empirical section and conclusion. Read how microstructure noise and frequency choice change realized-variance precision; frequency conclusions from that paper’s sample apply only to its sample and setting.
- Should Know — Patton (2011), §2 propositions and conclusion. Read the requirements for forecast-comparison losses with noisy but conditionally unbiased variance proxies; the proxy used in this chapter does not automatically meet them.
- Should Know — SciPy
minimize(method="SLSQP")official documentation. Learn the constrained-optimization API, stopping precision, and solver status; stopping precision does not prove a global optimum. - Optional — Official ARCH/GARCH forecast and EWMA API documentation. Use it to check one- and multi-step variance targets and alignment; this chapter does not install or use the
archestimator. - Advanced — Engle (1982). The original paper is the source of ARCH, but this work checked only the bibliographic information on the author’s official page and did not obtain the full paper. You may obtain it through an institutional library and check the specific test derivation; this chapter does not cite unread passages as authority.
20. References
- French Data Library. 10 Industry Portfolios, monthly average value-weighted returns. The original download URL is in the data manifest; the study snapshot, processing, and hashes are listed in Section 11. The table contains currently downloadable historical values, not historical point-in-time vintages.
- Bollerslev, T. (1986). “Generalized autoregressive conditional heteroskedasticity.” Journal of Econometrics, 31(3), 307–327. DOI: 10.1016/0304-4076(86)90063-1. This chapter checks the key moment conditions against §§2–3 of the author’s original journal PDF, physical PDF pages 3–6; the specific reading range is in
source_notes.md. - Andersen, T. G., Bollerslev, T., Diebold, F. X., & Labys, P. (2003). “Modeling and forecasting realized volatility.” Econometrica, 71(2), 579–625. DOI: 10.1111/1468-0262.00418. This chapter reads the Introduction and opening of §2; the derivation coverage is noted in the source notes.
- Hansen, P. R., & Lunde, A. (2006). “Realized variance and market microstructure noise.” Journal of Business & Economic Statistics, 24(2), 127–161. DOI: 10.1198/073500106000000071.
- Patton, A. J. (2011). “Volatility forecast comparison using imperfect volatility proxies.” Journal of Econometrics, 160(1), 246–256. DOI: 10.1016/j.jeconom.2010.03.034.
- Engle, R. F. (1982). “Autoregressive conditional heteroscedasticity with estimates of the variance of United Kingdom inflation.” Econometrica, 50(4), 987–1008. DOI: 10.2307/1912773. The full paper was not obtained for this work, so no specific theorem or within-paper step is attributed to it.
- SciPy documentation.
scipy.optimize.minimize, SLSQP method. Optimizer API and stopping criterion only. arch7.2 documentation. Forecasting; EWMA variance process. Documentation consulted for definitions and alignment; the estimator was not installed or used.
Source locations, historical reading ranges, and verification limits are detailed in source_notes.md.