CHAPTER 04/ 45
: Calculus, Rates of Change, Curvature and Local Decisions
Spine: use the response of a price to a yield change and the curvature of a portfolio objective to make a small change in inputs something you can calculate and check. Prerequisites: Chapter 2's Python and arrays. Section 6.3 develops column vectors, transposes and a two-by-two product before Chapter 5 collects the linear algebra. You will derive a constructed bond's first and second derivatives, read their units, and compare analytic and numerical derivatives of a quadratic objective.
1. Learning Objectives
Work from a one-variable rate of change to a local approximation with several inputs. You should be able to:
- Define a derivative by a limit of difference quotients and distinguish continuity, differentiability and twice continuous differentiability, written
. - Read a derivative's units from its input and output.
- Distinguish a partial derivative, total differential, gradient, directional derivative and Hessian matrix.
- State the smoothness and remainder conditions behind first- and second-order Taylor approximations.
- Accumulate marginal changes using the fundamental theorem of calculus.
- Classify an interior stationary point as a minimum, maximum or saddle when the second-order test applies, and recognize when it is inconclusive.
- Compare central differences with analytic gradients and Hessians, including the effects of step size.
The two constructed cases give concrete checks. The bond has
The portfolio case gives objective
2. Why Quantitative Research Needs Calculus
A yield rises by one basis point: how much does the formula price change? A feature changes: which way does a model score move? A portfolio weight changes: does its risk objective increase? Calculus separates the slope, the chosen direction and the curvature in each question.
A slope needs a shock size before it becomes a price change. In our bond case,
The gradient describes the local response; the Hessian describes how that response changes. A definite integral accumulates marginal responses along a path. These calculations describe the chosen mathematical model. Evidence for prediction, execution and costs must come from a research design that also addresses those questions.
3. Intuition: Slope and Curvature
Read
On a price-yield graph, put yield on the horizontal axis and price on the vertical axis. A tangent line at the current yield has slope
For
4. Mathematical Foundations: Increments, Units and Shapes
4.1 Variables, Function Inputs and Powers
The parentheses in
A power means repeated multiplication:
4.2 Input Increments and Difference Quotients
Change
For
Its units are output units divided by input units. For
Differentiability lets us separate a linear part from a smaller remainder:
The notation
4.3 Units and Dimensions
A derivative has units
Price uses currency units; yield is a dimensionless decimal. Accordingly,
A derivative reported per decimal yield unit is not a price change per percentage point or per bp.
With inputs
For
5. Definitions
A limit describes nearby function values. If for every
A partial derivative
At a differentiable point, the total differential is the linear part:
It approximates a small increment; it need not equal an arbitrary finite change.
For a unit direction
when
The Hessian collects second partial derivatives:
Under
A second-order Taylor expansion is
For
Here
An error
For continuous
If
A differentiable local extremum in an open region has zero gradient. At a stationary point of a locally
For differentiable functions and fixed constants,
A constant has derivative zero; the power rule
To derive the product rule, add and subtract
Existing partial derivatives need not imply multivariable differentiability. Define
6. Derivations: From a Bond Curve to a Portfolio Surface
6.1 Bond Derivatives and Yield Units
For our constructed bond,
The exponent reflects two annual discount periods. Write the outer rule as
The exponent moves into the coefficient and decreases by one; the inner derivative is 1.
Check directly from the definition. For
Cancel the nonzero
Throughout
6.2 Path Derivatives and Directional Derivatives
For a specified yield path
If
For a bond whose remaining maturity changes, use
In a smooth calendar-time scenario,
Let
price units per year. The path is specified for teaching, not estimated as a forecast.
For
At
face_value = 100.0
y0 = 0.05
yield_change_per_year = 0.002

def price(yield_rate: float) -> float:
    return face_value / (1.0 + yield_rate) ** 2

def yield_path(time_years: float) -> float:
    return y0 + yield_change_per_year * time_years

def price_path(time_years: float) -> float:
    return price(yield_path(time_years))

analytic_price_rate = (-200.0 / (1.0 + y0) ** 3) * yield_change_per_year
step_years = 1e-4
numeric_price_rate = (
    price_path(step_years) - price_path(-step_years)
) / (2.0 * step_years)

def g(x: float, z: float) -> float:
    return x**2 + 3.0 * z

g_rate = (2.0 * 1.0) * 1.0 + 3.0 * 2.0
dt = 0.01
exact_g_change = g(1.0 + dt, 2.0 * dt) - g(1.0, 0.0)
linear_g_change = g_rate * dt
print("bond price rate per year:", analytic_price_rate, numeric_price_rate)
print("g exact/linear change:", exact_g_change, linear_g_change)
assert abs(analytic_price_rate - numeric_price_rate) < 1e-8
assert abs(exact_g_change - 0.0801) < 1e-12
assert abs(linear_g_change - 0.08) < 1e-12
For a vector path,
If the gradient is nonzero, Cauchy-Schwarz gives the smallest derivative over Euclidean unit directions as
6.3 Gradient and Hessian of a Quadratic Objective
Use the teaching score
Both expected simple returns and covariance refer to the same annual interval and use decimals. A general mean-variance score has a risk-aversion coefficient:
That coefficient sets the trade-off and has inverse return units when preserving the return-unit interpretation. Here we fix its numerical value at 1 and suppress it for differentiation. The objective is a risk-return score, not a realized return. Changing decimals to percentages requires a corresponding coefficient change. Chapter 9 develops the convention; its English translation is pending a later batch.
For symmetric
The shapes in
Multiplying by
For example, the derivative of
Differentiate each gradient entry again:
The diagonal entries describe individual-coordinate curvature; .01 describes interaction between simultaneous changes. Along
For a budget-preserving transfer
6.4 Integrating a Marginal Price Response
Because
Price per yield unit times yield units returns price units. This is an exact accumulation within the formula; holding the initial slope fixed and multiplying by .01 would give a linear approximation. The negative integral means a net decline, not a negative price. Reversing the endpoints reverses the change's sign. Finer Riemann sums accumulate more local responses over the same interval.
6.5 Central Differences
For a sufficiently smooth scalar function,
Subtract and divide by
Under the stated smoothness, truncation error is
A large step averages over too much curvature. A very small step subtracts almost equal values and amplifies rounding; it may also divide simulation noise by a tiny number. Check neighboring step sizes for a stable range. One apparently perfect step is weak evidence. Near a parameter boundary, a central difference may call the function outside its legal domain; handle the boundary explicitly or use a justified one-sided method.
6.6 From a Descent Direction to a Finite Step
A negative directional derivative does not guarantee descent at every step size. For our fixed quadratic objective, let
The negative term grows linearly in the step; positive curvature grows quadratically. For positive definite
At our current weights,
The starting score is
This exact bound belongs to this fixed quadratic score. A general differentiable objective needs a suitably small step, local curvature checks or an explicit backtracking rule. Even the descending .1 step has weights summing to 1.006. Along the existing feasible direction
7. Financial Interpretation
In the portfolio score, gradient entry
The .1 update in Section 8.2 sums to 1.006. The transfer in Section 6.3 sums to zero as an increment and preserves the budget. For a budget-feasible small direction,
The fixed risk-aversion scaling makes the example a numerical score. Variance and expected return do not naturally have the same units. A financial mean-variance objective needs an explicit coefficient or normalization; these calculations cannot identify a particular investor's utility or preferences.
8. Numerical Examples
8.1 A Zero-Coupon Bond and One Basis Point
At
One bp gives linear change
The quadratic approximation restores curvature:
The curvature contribution is
import numpy as np
from quant_course.math_tools import finite_difference_gradient, finite_difference_hessian

face_value = 100.0
y = 0.05

def bond_price(point: np.ndarray) -> float:
    return face_value / (1.0 + point[0]) ** 2

price = bond_price(np.array([y]))
analytic_first = -2.0 * face_value / (1.0 + y) ** 3
analytic_second = 6.0 * face_value / (1.0 + y) ** 4
numeric_first = finite_difference_gradient(bond_price, [y], step=1e-4)[0]
numeric_second = finite_difference_hessian(bond_price, [y], step=1e-3)[0, 0]

print(f"price={price:.10f}")
print(f"first analytic/numeric={analytic_first:.10f}/{numeric_first:.10f}")
print(f"second analytic/numeric={analytic_second:.10f}/{numeric_second:.10f}")
assert np.isclose(price, 90.7029478458)
assert np.isclose(analytic_first, numeric_first, rtol=1e-6)
assert np.isclose(analytic_second, numeric_second, rtol=2e-6)
8.2 A Step on the Quadratic Surface
For
The quadratic term is
At learning rate
This particular step descends, but the weights sum to 1.006. Section 6.6 shows why a larger step can increase the score. Compare analytic and central-difference quantities in one place:
import numpy as np
from quant_course.math_tools import finite_difference_gradient, finite_difference_hessian

sigma = np.array([[0.04, 0.01], [0.01, 0.09]])
mu = np.array([0.05, 0.08])
weights = np.array([0.6, 0.4])

def objective(point: np.ndarray) -> float:
    return float(0.5 * point @ sigma @ point - mu @ point)

exact_gradient = sigma @ weights - mu
numeric_gradient = finite_difference_gradient(objective, weights)
numeric_hessian = finite_difference_hessian(objective, weights)
next_weights = weights - 0.1 * exact_gradient

print(f"f={objective(weights):.10f}")
print("gradient:", exact_gradient)
print("numeric gradient:", numeric_gradient)
print("numeric Hessian:\\n", numeric_hessian)
print("one unconstrained step:", next_weights)
print(f"new objective={objective(next_weights):.10f}")
assert np.isclose(objective(weights), -0.0452)
assert np.allclose(exact_gradient, [-0.022, -0.038])
assert np.allclose(numeric_hessian, sigma, atol=2e-7)
assert objective(next_weights) < objective(weights)
9. Python Implementation
Default Entry in the Accepted Reader Package
Follow the reader installation instructions. From its root, run:
.venv/bin/python run_notebook.py notebooks/ch04_calculus.ipynb
The default Notebook calls the packaged shared implementation, reads no absent French inputs and downloads nothing. New execution records and figures go to a unique runs subdirectory; reader CLI outputs use universally unique identifiers (UUIDs) and reject overwrites. Historical production tests that were not packaged remain references to original checks. Use the Notebook's assertions for the reader route. French inputs require the optional-data contract and were not rerun in this batch.
The separate original course route uses ch04_calculus.py, the Notebook, and shared src/quant_course/math_tools.py. Install its project environment, then run from the course root:
.venv/bin/python tools/run_a2.py --chapter 4
The deterministic formulas have no random seed, market observations, signal timestamp, trade timestamp or measured holding interval. A strategy application must establish input availability at signal_time, later execution at trade_time and returns from actual position activation.
The application programming interface (API) finite_difference_gradient takes a callable scalar function, a finite nonempty real vector and a step, defaulting to 1e-5; it returns a floating-point vector of the same length. finite_difference_hessian takes the same kind of inputs, defaults to 1e-4, and returns a square matrix matching the input dimension. Every perturbed function call must return a finite real scalar. NaN, infinity, complex or nonnumeric inputs cause explicit errors. A shared default step is a starting point; inspect coordinate scales and stability.
Hessian diagonals use gradient is a different interface for sampled arrays: central differences inside, one-sided differences at boundaries, preserving shape. Supply the actual coordinates rather than treating each gap as one:
import numpy as np

time_years = np.array([0.0, 0.4, 1.0, 1.8, 3.0])
values = time_years**2
estimated_slope = np.gradient(values, time_years)
print("time in years:", time_years)
print("sampled function:", values)
print("estimated derivative:", estimated_slope)
assert np.isclose(estimated_slope[2], 2.0)
10. Visualization: Error Orders and Floating-Point Limits
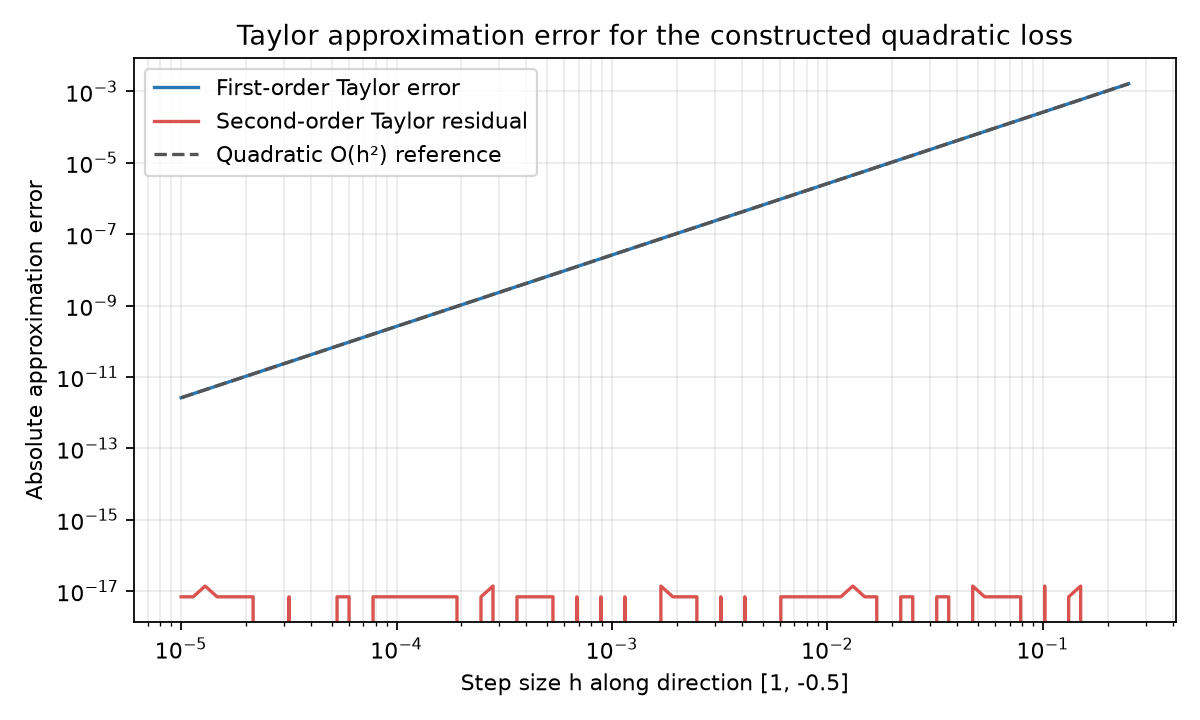
The horizontal axis is step
Compare slopes and the plateau. The plateau does not establish a feature of the exact function. This is neither a yield curve nor measured market-price error. The bond outputs support hand calculations; the figure supports the approximation-error lesson.
11. From Constructed Formulas to Market Research
This chapter has not downloaded or analyzed bond prices, curves or cash flows. It has no empirical period, market frequency, data authorization, market-version hashes or market result. Face value 100, two-year maturity and 5% annual-compounding yield are teaching assumptions.
A fixed-income study needs security identity, coupons and payment dates, day count, yield compounding, clean or dirty price, curve source, timestamps and versions. Real cash flows require their respective discount periods; a single yield and factor need not suffice. Credit spreads, curve changes, liquidity and accrued interest affect quotes.
Specify security selection, quote observation times, yield-price matching, duplicates, missingness, accrual and cash-flow mapping to curve nodes. Check a fitted sensitivity on another period or other securities. Without those records the derivation explains a model implication rather than how the market behaved. Later financial chapters develop duration, convexity and market data; their English editions are pending later batches.
12. Common Mistakes
12.1 Calling .01 a One-Basis-Point Shock
Decimal yields require .0001 for one bp. The negative assertion below demonstrates that .01 is a different shock; an assertion that the two shocks were equal would fail.
import numpy as np

y = 0.05
dy_wrong = 0.01
dy_one_bp = 0.0001
price = lambda rate: 100.0 / (1.0 + rate) ** 2

wrong_change = price(y + dy_wrong) - price(y)
one_bp_change = price(y + dy_one_bp) - price(y)
print(f"wrongly labeled one bp: {wrong_change:.10f}")
print(f"actual one bp: {one_bp_change:.10f}")
assert not np.isclose(dy_wrong, dy_one_bp)
assert np.isclose(one_bp_change, -0.0172742842, atol=1e-10)
The exact one-bp change is
12.2 Omitting Parentheses in a Difference Quotient
12.3 Treating a Quadratic Taylor Polynomial as an Exact Formula
A second-order Taylor expression needs its remainder except when the function's form makes the remainder zero. At zero, approximating
import math

x = 0.5
approximation = 1.0 + x + x**2 / 2.0
exact = math.exp(x)
error = exact - approximation
print(f"quadratic approximation={approximation:.10f}")
print(f"exact value={exact:.10f}")
print(f"omitted remainder={error:.10f}")
assert error > 0.0
The polynomial is 1.625; the exact value is about 1.6487212707; the omitted remainder is about .0237212707.
12.4 Calling Every Zero Gradient a Minimum
At the origin,
import numpy as np

def saddle(point: np.ndarray) -> float:
    return float(point[0] ** 2 - point[1] ** 2)

origin = np.array([0.0, 0.0])
gradient = np.array([2.0 * origin[0], -2.0 * origin[1]])
hessian = np.array([[2.0, 0.0], [0.0, -2.0]])
wrongly_called_minimum = np.allclose(gradient, 0.0)
eigenvalues = np.linalg.eigvalsh(hessian)
rise = saddle(np.array([0.1, 0.0])) - saddle(origin)
fall = saddle(np.array([0.0, 0.1])) - saddle(origin)
print("gradient:", gradient, "naive minimum label:", wrongly_called_minimum)
print("Hessian eigenvalues:", eigenvalues, "directional changes:", rise, fall)
assert wrongly_called_minimum
assert eigenvalues[0] < 0.0 < eigenvalues[1]
assert rise > 0.0 and fall < 0.0
12.5 Treating an Unconstrained Step as a Feasible Portfolio
The Section 8.2 step sums to 1.006. Specify constraints before choosing a projected update or feasible direction. The example retains the wrong unconstrained update for comparison and separately checks a budget-preserving step.
import numpy as np

sigma = np.array([[0.04, 0.01], [0.01, 0.09]])
mu = np.array([0.05, 0.08])
weights = np.array([0.6, 0.4])

def objective(point: np.ndarray) -> float:
    return float(0.5 * point @ sigma @ point - mu @ point)

gradient = sigma @ weights - mu
unconstrained = weights - 0.1 * gradient
feasible_direction = np.array([-1.0, 1.0])
feasible = weights + 0.01 * feasible_direction
print("unconstrained weights/sum:", unconstrained, unconstrained.sum())
print("feasible weights/sum:", feasible, feasible.sum())
print("starting/feasible objective:", objective(weights), objective(feasible))
assert not np.isclose(unconstrained.sum(), 1.0)
assert np.isclose(feasible.sum(), 1.0)
assert np.all(feasible >= 0.0)
assert objective(feasible) < objective(weights)
12.6 Comparing Gradients Across Different Coordinate Units
A gradient mixing percentage-point and ratio coordinates mixes units. Specify scaling and its effects on gradients, Hessians and steps. Changing units changes the numerical optimization path, not the economic question. Here the derivative per bp is one ten-thousandth of the derivative per decimal unit, while the same physical shock has the same impact:
import numpy as np

y = 0.05
one_basis_point_in_decimal = 0.0001
price = lambda rate: 100.0 / (1.0 + rate) ** 2
derivative_per_decimal = -200.0 / (1.0 + y) ** 3
derivative_per_basis_point = derivative_per_decimal / 10000.0
impact_from_decimal_coordinate = derivative_per_decimal * one_basis_point_in_decimal
impact_from_bp_coordinate = derivative_per_basis_point * 1.0
print("derivative per decimal unit:", derivative_per_decimal)
print("derivative per basis point:", derivative_per_basis_point)
print("same shock impact:", impact_from_decimal_coordinate, impact_from_bp_coordinate)
assert np.isclose(impact_from_decimal_coordinate, impact_from_bp_coordinate)
12.7 Omitting Path Speed from the Chain Rule
import numpy as np

y = 0.05
yield_change_per_year = 0.002
derivative_price_per_yield = -200.0 / (1.0 + y) ** 3
wrong_price_rate = derivative_price_per_yield
correct_price_rate = derivative_price_per_yield * yield_change_per_year
print("wrong units/value:", wrong_price_rate, "price per yield unit")
print("chain-rule rate:", correct_price_rate, "price per year")
assert not np.isclose(wrong_price_rate, correct_price_rate)
assert np.isclose(correct_price_rate, -0.3455350394)
13. Connecting Local Calculations to Research Decisions
State the objective, units, frequency and estimation window. Compute its value, gradient and Hessian. A candidate direction with
Estimate
Keep input checks, derivative comparisons, stationarity classifications, feasibility and out-of-sample performance as separate checks. Success of one cannot fill missing evidence for another. Fees, impact and data availability can change the entire objective's relevance to executable decisions.
14. Chapter Summary
Derivatives give local rates in specified units. The chain rule combines input sensitivities with path speeds. Gradients collect coordinate rates and Hessians describe curvature. Taylor approximations require their smoothness and remainder conditions; integrals accumulate marginal responses under the fundamental theorem's conditions.
The constructed bond slopes downward and curves upward. The quadratic portfolio score has gradient
15. Exercises
4-N01: Inputs and Difference Quotients
For
4-N02: Bond Derivatives and Basis Points
Set
4-N03: Diagnose a Slope Labelled as a Price Change
The following code claims to report a one-bp price change. Explain the mismatch between its name and value. Replace it with a linear price-change approximation and check against the difference of formula prices.
def price(y):
    return 100.0 / (1.0 + y) ** 2

y = 0.05
one_bp = 0.0001
reported_price_change = (price(y + one_bp) - price(y)) / one_bp
assert abs(reported_price_change + 172.7675) < 0.1
4-N04: Model Implications and Market Evidence
A researcher uses
4-E01: Continuity and Differentiability
Explain why differentiability implies continuity. Give a continuous but nondifferentiable function, identify the point, and compare its left and right difference quotients.
4-E02: Yield-Shock Units
Convert 1, 25 and 100 bp to decimal increments. If a program uses .01 for one bp, how many bp does it actually apply?
4-E03: A Price Slope
Derive
4-E04: Total Differential and Chain Rule
For
4-E05: Unit Directions
Explain normalization when comparing directional derivatives. Normalize
4-E06: Gradient and Hessian
Find both for
4-E07: Taylor Remainders
Which smoothness is needed for a third-order Lagrange remainder after a second-order expansion? What changes for a quadratic polynomial?
4-E08: Stationary-Point Classification
Give two-variable functions with a local minimum, local maximum and saddle at zero, checking their gradients and Hessians.
4-E09: Accumulating a Marginal Change
Compute
4-B01: Direction and Finite Step Size
For the existing quadratic score at
16. Programming Exercises
4-P01: Check Bond Differences
At
4-P02: Check the Quadratic Score
Using the chapter's
4-P03: Sampled Derivatives and Integrals
Sample gradient and check the interior derivative. Approximate
17. Challenge Problems
4-C01: Choosing a Yield-Shock Approximation
From yield .05, compare exact, linear and quadratic changes for rises of 1, 25 and 100 bp. Declare a repeatable tolerance and decide which approximations meet it. Distinguish floating-point error from model error.
Ten points: units/shocks 2, exact and approximate values 3, error/tolerance 2, small/large-step interpretation 2, constructed rather than market identity 1. No single tolerance is mandatory; a reproducible rule is.
4-C02: Add a Full-Investment Budget
Solve
Explain why
Twelve points: unconstrained/budget conflict 2, Lagrange derivation 3, nonnegative boundary analysis 3, numerical/analytic result 2, feasibility/objective verification 2. Bare library output without constraints and verification earns at most 4.
18. Complete Solutions
4-N01
The quotient has output/input units and is the average rate on
Take the limit through nonzero increments.
4-N02
With
At .05, these are
price units. The negative response belongs to the formula and does not predict yield movement.
4-N03
Dividing a price change by a yield change produces an average rate, not a one-bp price change. The assertion tests closeness of the quotient to the derivative within .1. Its variable name cannot change its units. Multiply the analytic slope by the shock for a linear approximation; subtract the two prices for the exact constructed change:
def price(y):
    return 100.0 / (1.0 + y) ** 2

y = 0.05
one_bp = 0.0001
slope = -200.0 / (1.0 + y) ** 3
linear_price_change = slope * one_bp
exact_price_change = price(y + one_bp) - price(y)
assert abs(linear_price_change - (-0.01727675197063)) < 1e-12
assert abs(exact_price_change - (-0.0172742842)) < 1e-10
The linear change is about
4-N04
The derivative is a local slope of a single-cash-flow, two-year, annual-compounding rule at 5%. Given a one-bp rise, it supports a linear change of about
Record identity, coupons, cash-flow dates, remaining maturity, day count, compounding, clean/dirty quote convention, quote source and observation time, yield-price matching and version. A future-price claim also needs information-timed evidence for yield direction, costs and position activation.
4-E01
Write
As
4-E02
The increments are .0001, .0025 and .01. Labelling .01 as one bp applies 100 bp, a hundredfold shock and an absolute error of 99 bp.
4-E03
4-E04
4-E05
An unnormalized vector mixes direction and speed in
4-E06
Leading minor 2 and determinant 7 are positive. The strictly convex quadratic has its unique global and strict local minimum at its stationary point
4-E07
Third differentiability along the segment is needed for the intermediate-point Lagrange expression; a uniform bound also needs bounded third derivatives. A quadratic equals its second-order Taylor polynomial, so the third-order remainder is zero.
4-E08
4-E09
The marginal response
4-P01: Reference Implementation
Run in the project's frozen environment. Define the teaching function locally and compare both derivative orders:
import numpy as np
from quant_course.math_tools import finite_difference_gradient, finite_difference_hessian

face_value = 100.0
y = 0.05
price = lambda point: face_value / (1.0 + point[0]) ** 2
exact_first = -2.0 * face_value / (1.0 + y) ** 3
exact_second = 6.0 * face_value / (1.0 + y) ** 4
numeric_first = finite_difference_gradient(price, [y], step=1e-4)[0]
numeric_second = finite_difference_hessian(price, [y], step=1e-3)[0, 0]
one_bp = price(np.array([y + 0.0001])) - price(np.array([y]))
one_hundred_bp = price(np.array([y + 0.01])) - price(np.array([y]))

print("price:", price(np.array([y])))
print("first:", exact_first, numeric_first)
print("second:", exact_second, numeric_second)
print("1 bp exact price change:", one_bp)
print("100 bp exact price change:", one_hundred_bp)
assert np.isclose(exact_first, -172.7675197063)
assert np.isclose(exact_second, 493.6214848751)
assert np.isclose(numeric_first, exact_first, rtol=1e-6)
assert np.isclose(numeric_second, exact_second, rtol=2e-6)
assert np.isclose(one_bp, -0.0172742842, atol=1e-10)
assert np.isclose(one_hundred_bp, -1.7033038444, atol=1e-10)
4-P02: Reference Implementation
The snippet defines its inputs. Central differences check the analytic gradient that supplies the update direction:
import numpy as np
from quant_course.math_tools import finite_difference_gradient, finite_difference_hessian

sigma = np.array([[0.04, 0.01], [0.01, 0.09]])
mu = np.array([0.05, 0.08])
weights = np.array([0.6, 0.4])

def objective(point: np.ndarray) -> float:
    return float(0.5 * point @ sigma @ point - mu @ point)

gradient = sigma @ weights - mu
numeric_gradient = finite_difference_gradient(objective, weights)
hessian = finite_difference_hessian(objective, weights)
new_weights = weights - 0.1 * gradient
print("objective:", objective(weights))
print("gradient:", gradient)
print("numeric gradient:", numeric_gradient)
print("numeric Hessian:\\n", hessian)
print("new weights:", new_weights, "sum:", new_weights.sum())
print("new objective:", objective(new_weights))
assert np.isclose(objective(weights), -0.0452)
assert np.allclose(gradient, [-0.022, -0.038])
assert np.allclose(numeric_gradient, gradient, atol=1e-9)
assert np.allclose(hessian, sigma, atol=2e-7)
assert objective(new_weights) < objective(weights)
assert not np.isclose(new_weights.sum(), 1.0)
The final assertion deliberately shows the budget violation. A descending program objective has not solved the constrained problem.
4-P03: Reference Implementation
Use actual nonuniform coordinates. Refine midpoint intervals to check error reduction against the analytic integral:
import numpy as np

nodes = np.array([0.0, 0.4, 1.0, 1.8, 3.0])
samples = nodes**2
derivative = np.gradient(samples, nodes)
print("interior derivative at x=1:", derivative[2])
assert np.isclose(derivative[2], 2.0)

def midpoint_integral(n: int) -> float:
    edges = np.linspace(0.0, 1.0, n + 1)
    midpoints = (edges[:-1] + edges[1:]) / 2.0
    width = 1.0 / n
    return float(np.sum(midpoints**2) * width)

exact = 1.0 / 3.0
errors = [abs(midpoint_integral(n) - exact) for n in (10, 100, 1000)]
print("midpoint errors:", errors)
assert errors[0] > errors[1] > errors[2]
The exact integral is
4-C01: Values and a Repeatable Decision Rule
| Decimal yield change | Basis points | Exact change | Linear change | Quadratic change |
|---|---|---|---|---|
| .0001 | 1 | -.0172742842 | -.0172767520 | -.0172742839 |
| .0025 | 25 | -.4303811146 | -.4319187993 | -.4303762321 |
| .0100 | 100 | -1.7033038444 | -1.7276751971 | -1.7029941228 |
An absolute price-error tolerance of .001 accepts all three quadratic approximations and rejects the linear 100-bp approximation. At a relative tolerance of .1% of the exact change, the 100-bp quadratic error is about .0182% and passes; the linear error is about 1.43% and fails. Declare the threshold first and inspect neighboring shocks.
Roundoff arises from finite precision, often creating an error plateau at tiny steps. Model error arises from wrong cash flows, yield conventions or economic assumptions. A smaller difference step may alter the former without repairing the latter. These figures measure the constructed formula's approximations, not a real bond's quote errors.
4-C02: Derivation and Candidate Optimum
The unconstrained stationarity equation is
Its sum is about 1.82857, violating the budget. With the equality constraint, use
Stationarity gives
The values are
Both weights are nonnegative. Positive definiteness gives a strictly convex score on the convex feasible set, making this the unique long-only global optimum as well. Boundary scores are
import numpy as np

sigma = np.array([[0.04, 0.01], [0.01, 0.09]])
mu = np.array([0.05, 0.08])
ones = np.ones(2)
sigma_inverse_mu = np.linalg.solve(sigma, mu)
sigma_inverse_ones = np.linalg.solve(sigma, ones)
lagrange_multiplier = (ones @ sigma_inverse_mu - 1.0) / (ones @ sigma_inverse_ones)
weights = np.linalg.solve(sigma, mu - lagrange_multiplier * ones)

def objective(point: np.ndarray) -> float:
    point = np.asarray(point, dtype=float)
    return float(0.5 * point @ sigma @ point - mu @ point)

kkt_residual = sigma @ weights - mu + lagrange_multiplier * ones
print("lambda:", lagrange_multiplier)
print("constrained weights:", weights)
print("KKT stationarity residual:", kkt_residual)
print("sum:", weights.sum(), "objective:", objective(weights))
print("boundary objectives:", objective([1.0, 0.0]), objective([0.0, 1.0]))
assert np.isclose(weights.sum(), 1.0)
assert np.allclose(kkt_residual, np.zeros(2), atol=1e-12)
assert np.isclose(objective(weights), -0.0463636364)
assert np.all(weights >= 0.0)
assert objective(weights) < min(objective([1.0, 0.0]), objective([0.0, 1.0]))
In higher dimensions inspect active zero-weight boundaries and the Karush-Kuhn-Tucker (KKT) complementary-slackness conditions. Check primal feasibility, stationarity/dual conditions and the objective; a solver's success status alone is insufficient.
4-B01
Substitute
Strict descent requires
Along
19. Further Reading
- Must know: MIT 18.01SC sessions 3-5 and 48 for rates, limits, continuity and the fundamental theorem.
- Must know: MIT 18.02SC sessions 26-30 and 32-38 for partial derivatives, tangent approximations, optimization, chain rule, differentials and directions.
- Should know: NumPy
gradientdocumentation for coordinate spacing and interior/boundary formulas. - Advanced: Boyd and Vandenberghe, Convex Optimization, Section 3.1 and Chapter 9 for optimality conditions and descent methods.
- Optional: MIT 18.01SC Taylor's Formula resources for one-variable expansions and remainders.
20. References and Reading Boundaries
The inherited sources, exact URLs, verification methods and limits appear in the Chinese source audit record. The original exposition and derivations explain the mathematics; MIT OpenCourseWare supports topic placement and formula structure, Boyd supports convex optimality conditions, and NumPy supports sampled-array difference semantics. The bond and quadratic numbers are constructed by the author. No new external-document reading, market data download or market execution took place for this translation.